Key Takeaways
Actionable Strategies for Handling API Rate Limiting During Load Testing
If you want to avoid API rate limiting headaches during load testing, start by proactively monitoring usage patterns. Use real-time metrics to catch spikes before they trigger throttling. Tools like LoadFocus make it easier to visualize these patterns and pinpoint problematic clients or endpoints. Review how you structure requests – batching similar calls together and caching predictable responses can cut down on redundant traffic and ease pressure on the API.
Implement smart client behaviors. Exponential backoff and adaptive retry logic help your tests respect rate limiting headers and avoid immediate repeat failures. Don’t ignore “retry-after” responses – build your scripts to listen and adapt. If your API supports it, switch on batching and use local caching wherever possible. For guidance on improving your API test logic, see this practical optimization guide.
Is Your Infrastructure Ready for Global Traffic Spikes?
Unexpected load surges can disrupt your services. With LoadFocus’s cutting-edge Load Testing solutions, simulate real-world traffic from multiple global locations in a single test. Our advanced engine dynamically upscales and downscales virtual users in real time, delivering comprehensive reports that empower you to identify and resolve performance bottlenecks before they affect your users.
Provider-specific rules matter. Some APIs allow short bursts above the regular limit (for example, a quick spike up to 1000 requests per minute), while others enforce a strict ceiling. Study the documentation and, during critical tests, reach out to the provider to negotiate higher limits or request dedicated endpoints for high-volume operations. If you face persistent limits, consider spreading load across multiple API keys – if the provider’s policy allows.
Ultimately, balancing load testing thoroughness with respect for API rate limiting policies is key to reliable, actionable results. For more on detecting and troubleshooting common issues, this overview of API performance issues is a solid next read.
Selecting the Right Lens: Why API Rate Limiting Fails Load Tests
The Real Test: Traffic Pattern Meets Policy
When teams talk about load testing APIs, the conversation often starts with volume. How many requests per second can your backend handle? But sending more traffic is not the endgame. The critical line between a meaningful load test and a failed one is whether your test scenario actually reflects the API rate limiting policies you face in production. If your simulation ignores real-world rate limits – say, 1000 requests per minute per user, a number enforced by many providers – your results will be unreliable at best, and dangerously misleading at worst.
Think your website can handle a traffic spike?
Fair enough, but why leave it to chance? Uncover your website’s true limits with LoadFocus’s cloud-based Load Testing for Web Apps, Websites, and APIs. Avoid the risk of costly downtimes and missed opportunities—find out before your users do!
Key Insight: The real value of a load test comes from modeling not just system capacity, but how your system adapts when faced with real-world API rate limiting barriers.
Why “More Traffic” Misses the Point
It’s easy to launch a brute-force load test: crank up request volume until something breaks. But APIs are rarely taken down by raw traffic alone. Instead, they are protected by rate limiting rules designed to keep service stable during spikes. These rules act as a gatekeeper, throttling or outright blocking clients that exceed set thresholds. If your load test scenario sends traffic in a pattern that would never happen from real users – or piles all requests through a single account – you’re testing the wrong thing. You’ll simply hit the limit, collect 429 errors, and learn nothing about how your application recovers or degrades under realistic load.
Misaligned scenarios are especially common when teams fail to account for modern rate limiting strategies. Many APIs now use advanced algorithms like token bucket or dynamic limits that change based on system state, user tier, or even endpoint. A naive test that “spams” a single endpoint can’t tell you how your app will behave when only a subset of requests are throttled, or when retry-after headers change in real time.
Design Tests That Reflect Production Constraints
Effective load testing is about more than measuring throughput. You need to simulate authentic usage patterns – multiple users, variable request rates, realistic think time – that will trigger rate limits as they actually occur. When your tool, such as LoadFocus, lets you import traffic traces or model sessions with multiple API keys, you get closer to production truth. It’s also the only way to test your system’s resilience: does it back off gracefully, queue requests, or flood the server until it’s blacklisted?
For deeper insights, combine load testing with continuous API monitoring. This helps you correlate load patterns with rate limit triggers in real time, rather than only reviewing logs after the fact. And if you’re looking for practical strategies to overcome these hurdles, the API performance testing challenges guide covers proven approaches to both detect and adapt to provider-side constraints.
LoadFocus is an all-in-one Cloud Testing Platform for Websites and APIs for Load Testing, Apache JMeter Load Testing, Page Speed Monitoring and API Monitoring!
Ultimately, the right lens for load testing isn’t just about how much traffic you can throw at an API, but how intelligently your system handles the inevitable reality of rate limiting – and how well your test predicts what will happen when policies, not just capacity, are your bottleneck.
API Rate Limiting Causes at a Glance: Comparison Table
API rate limiting is rarely caused by just one factor during high traffic. Instead, it results from a mix of provider-imposed safeguards and client-side behaviors that can push an API beyond its limits. The table below offers a quick, practical comparison of the most common causes, illustrating their strengths, weaknesses, best-fit scenarios, and typical pricing implications. Use this as a reference point to identify which issue may be at play during your own load testing or production use.
| Cause Name | Key Strength | Key Limitation | Best For | Pricing Model |
|---|---|---|---|---|
| Exceeding Request Volume Thresholds (Provider-Side) | Protects backend stability during unpredictable spikes | Can block legitimate traffic if thresholds are static or too low | Preventing overload during load testing or unexpected surges | Often tied to usage tiers or pay-per-use |
| Inefficient or Redundant API Calls (Client-Side) | Easy to spot and fix through code review and monitoring | May trigger rate limits quickly, especially with poor caching | Early-stage apps or tests lacking request optimization | No direct cost, but leads to hidden infrastructure expense |
| Ignoring Rate Limit Headers & Retry Guidance (Client-Side) | Allows rapid API exploration or brute-force testing | Leads to immediate throttling or failed requests | Scripts/tools not designed for production traffic patterns | May incur penalties or temporary bans at higher usage |
| Provider-Side Adaptive or Burst Rate Limiting | Balances burst handling with sustained control | Algorithm complexity can make limits less predictable | APIs needing both flexibility and protection (e.g., e-commerce events) | Dynamic; can shift with real-time load or user segment |
| Subscription Tier or Quota Restrictions (Provider-Side) | Enables fine-grained access control by user level | Can create friction for high-growth clients | APIs with freemium, commercial, or enterprise plans | Usually tiered, with paid upgrades for higher limits |
| Aggressive Polling & Poor Pagination (Client-Side) | Simple to implement for real-time needs | Quickly exhausts rate limits and degrades performance | High-frequency apps ignoring event-driven alternatives | Can result in overage charges or throttling |
Some causes are squarely under the provider’s control – static thresholds and adaptive algorithms are set to protect backend infrastructure. Others, like redundant requests or ignoring headers, are rooted in client implementation. Reviewing your API usage patterns and optimizing your code can often prevent premature rate limiting. For a practical deep-dive on optimizing performance under load, see our API performance testing challenges guide.
1. Exceeding Request Volume Thresholds
Among all the triggers for API rate limiting, none is more frequent or fundamental than clients simply sending too many requests in too short a span. Providers set up hard request caps per user, token, or API key – often something like 1000 requests per minute per user – to keep the infrastructure stable under pressure. If your app or test script bursts beyond that ceiling, those extra requests start hitting a wall: they’re throttled, delayed, or outright rejected.
Key Insight: Most rate limiting issues in load testing come from sending request bursts that outpace what the API provider is actually willing to serve at any given moment.
This isn’t just a concern for production traffic. Load testing tools like LoadFocus are designed to help you simulate real-world demand, but if you don’t configure your test scenarios with provider thresholds in mind, you’re likely to trip those same defenses. What starts as a test of your system’s capacity can quickly become an unintentional simulation of a denial-of-service attack – hardly the insight you wanted.
Static vs. Dynamic Limits: Explains the Difference and Why It Matters for Test Planning
Understanding the difference between static and dynamic request thresholds is essential when planning test scenarios that won’t just bounce off the rate limiter. Static limits are straightforward: the provider sets a fixed cap (say, 1000 requests per minute), and exceeding it results in instant throttling or rejection. These are easy to plan for, but they’re also blunt tools. They don’t care whether your traffic spike is a one-off or a sustained attack; cross the line, and you’re out.
Dynamic limits add a layer of sophistication. Instead of a single hard cap, the threshold might flex based on current system load, user behavior, or even your subscription tier. Algorithms like token bucket or leaky bucket let APIs tolerate short bursts, as long as your average request rate stays within bounds. Some providers now adjust limits in real time, lowering thresholds during peak hours or for users behaving suspiciously. If you’re designing a load test, you need to know which model you’re dealing with. A static limit means you can throttle your test clients accordingly. A dynamic approach requires monitoring for subtle limit signals – and being ready to adapt on the fly.
For a deeper look at adaptive models and their impact on performance assessments, the Top 6 API Performance Testing Challenges post breaks down common API bottlenecks and how to spot them before they derail your tests.
How to Detect and Respond: Practical Steps for Identifying Excess Volume Patterns and Adjusting Test Scenarios
The first sign you’ve crossed a threshold is usually a sudden spike in 429 (Too Many Requests) errors or a drop in response quality. Effective API monitoring – built into platforms like LoadFocus – helps you spot these patterns as they happen. Start by tracking response headers: most providers include rate limit status headers that tell you how close you are to the cap. If you see rapid depletion of your request quota, pause the test and review your configuration.
It’s also worth examining your test plan for unintentional bursts. Are your virtual users all ramping up at once? Did you forget to stagger request intervals? Sometimes, what looks like an API’s weakness is really just a flaw in the test script. You’ll find more on structuring efficient load tests in the How to Load Test RESTful APIs with LoadFocus guide, which covers practical strategies for pacing and distribution.
Finally, don’t overlook the value of communication. If your application has legitimate high-volume needs – especially during business-critical events – reach out to the provider in advance. Many offer dedicated endpoints or custom rate plans to accommodate serious volume, as discussed in the API latency reduction case study. The main point: respecting limits – and showing you understand how they work – is the fastest way to keep your tests and your users running smoothly.
2. Inefficient or Redundant API Calls
One of the fastest routes to API rate limiting headaches is a client that fires off more requests than necessary. Redundant calls, like repeated polling or failing to store recent responses, can chew through a provider’s thresholds in minutes. This isn’t just a theoretical concern – real-world testing often reveals that most rate limit breaches are driven not by legitimate spikes in user activity, but by inefficient application logic that makes the same call multiple times when a single response would suffice.
Consider a dashboard that reloads every data widget independently, each polling the backend every few seconds. If those widgets request overlapping data, or if the app neglects to cache unchanged responses, you’re effectively multiplying your API usage for no real benefit. LoadFocus’s guide to common API performance issues spells out how these patterns surface in testing and why they’re so costly.
Before/After Example: Optimizing Call Patterns
| Before | After |
|---|---|
|
Naive Polling: Every client widget polls the API every 5 seconds, asking for the same data, regardless of whether it changed. Example: Five widgets, each making their own GET /status call = 60 requests per minute, even if nothing is new. |
Batched & Cached: The client fetches all needed data in a single call and caches the response. Widgets read from the cache and only refresh if a change is detected. Example: One batched GET /status_all call every 30 seconds. Response cached and shared across widgets = 2 requests per minute. |
Optimizing call patterns this way slashes unnecessary traffic, minimizes risk of hitting rate limits, and often delivers a snappier user experience. It’s not just about the volume of requests – it’s about making sure each one counts.
Batching requests and using client-side caching are two of the simplest yet most effective ways to keep your API consumption under control. By grouping multiple queries into a single call (when the API supports it) or by storing recent responses locally, you avoid hammering the server with duplicate requests. This technique is especially valuable when working with APIs that enforce strict per-user or per-token rate limits, such as the 1000 requests/minute threshold described in LoadFocus’s API performance issues article.
But how do you spot these inefficiencies? That’s where API testing tools come in. Advanced platforms like LoadFocus’s API tester can simulate real-world load, visualize request patterns, and pinpoint wasteful behaviors. If you see a flood of identical requests or excessive retries, it’s a signal to revisit your client logic.
Addressing redundant calls is rarely about sophisticated algorithms. It’s about discipline: cache what you can, batch what you must, and let your API (and rate limits) breathe a little easier.
3. Ignoring Rate Limit Headers and Retry Guidance
One of the most common, yet avoidable, mistakes in load testing APIs is failing to respect the explicit feedback provided in response headers. Nearly every modern API signals its rate limiting status through headers – think X-RateLimit-Remaining or Retry-After. Ignoring these signals is a fast track to a flood of 429 (Too Many Requests) errors that can distort your test results and even mask actual performance issues.
Consider the scenario: your test client hits an endpoint repeatedly, surpassing the provider’s public threshold (1000 requests per minute, for example). The API responds with a 429 and a Retry-After: 60 header, clearly telling your client to pause. If your load testing tool (or custom script) doesn’t parse and act on this, it will continue hammering the endpoint, racking up more rejections. Instead of learning how the backend performs under load, you end up measuring how quickly your test can irritate the rate limiter.
This is not a trivial oversight. APIs increasingly use sophisticated and adaptive rate limiting techniques, such as token bucket models, which tolerate occasional bursts but clamp down hard on sustained overuse. Many providers also tailor limits dynamically, raising or lowering them based on your usage patterns or subscription tier. Missing or mishandling rate limit headers doesn’t just cause unnecessary test noise, it prevents you from understanding how real-world clients will fare during peak use. For more on diagnosing these types of issues, see 10 Common API Performance Issues and How to Detect Them.
Key Insight: Ignoring rate limit and retry headers in API responses leads to a flood of 429 errors and completely undermines your ability to test real-world performance under load.
Automated handling of these headers is not just a best practice – it’s essential. If your load test suite or API monitoring tool doesn’t support header-aware retries and backoff, you’re not getting an accurate picture. Tools like LoadFocus are designed to surface these patterns and give you real-time feedback on how your application behaves when limits are reached, supporting you as you tune both client and server for peak efficiency. For guidance on structuring your load tests to reflect production realities, review 10 Ways to Optimize API Performance Testing for Faster, More Reliable Results.
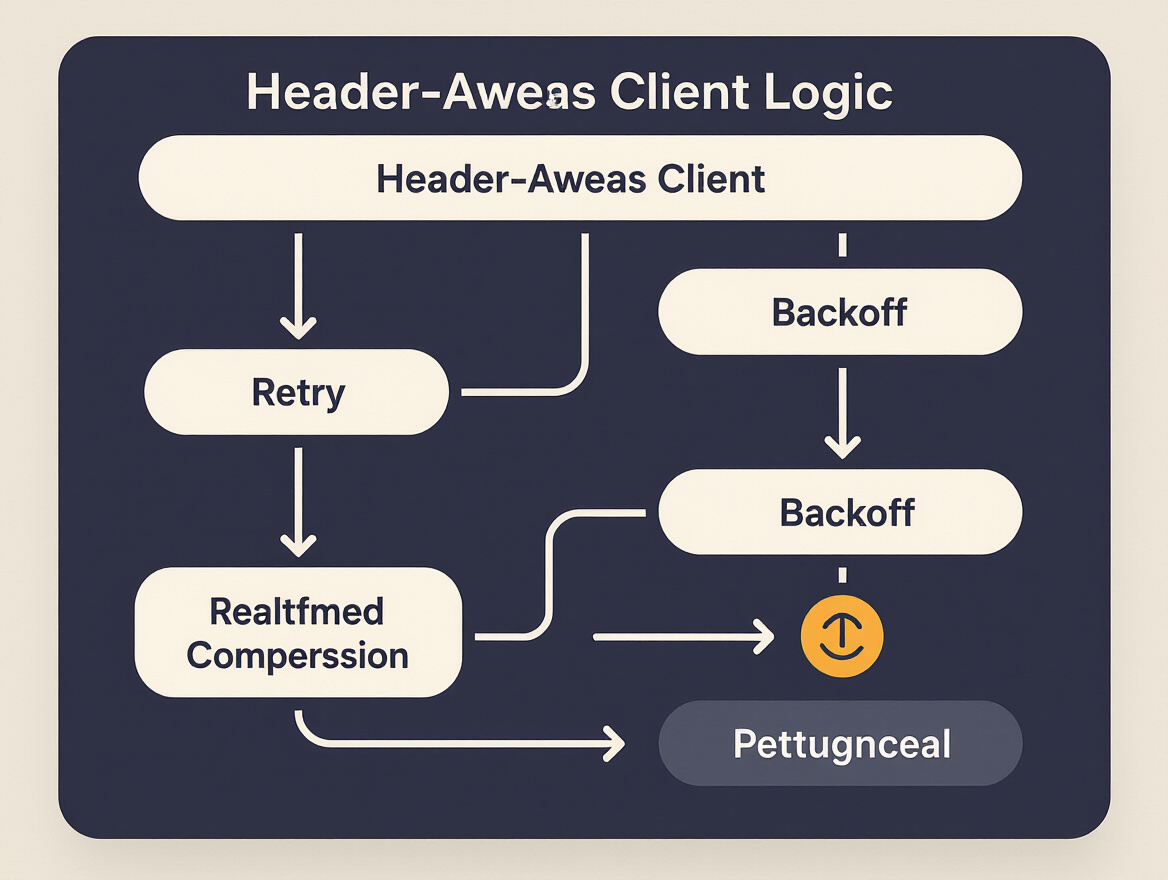
How to Implement Header-Aware Clients: Best Practices for Parsing and Acting on Rate Limit Information
Ensuring your clients behave responsibly under load means actively parsing and responding to rate limit headers. Here are a few best practices:
- Parse all relevant headers (
Retry-After,X-RateLimit-Remaining, etc.) in every response. Do not assume the same format across providers. - Implement automatic backoff – if you receive a 429 with a
Retry-Afterheader, respect the pause before sending the next request. Use exponential backoff if no guidance is given. - Log all rate limit events during load testing. This lets you distinguish between genuine performance bottlenecks and self-inflicted throttling.
- Test with multiple identities (API keys, user tokens) if permitted, to better distribute load and simulate real-world access patterns.
By making your test clients header-aware, you not only avoid unnecessary API rejections but also generate data that mirrors realistic production scenarios. Overlooking this step can render even the most sophisticated load tests misleading, undermining both your technical insights and your case for performance improvements.
4. Aggressive Polling and Poor Pagination Handling
How Excessive Requests Quickly Trigger API Rate Limiting
One of the most common pitfalls in API performance testing is aggressive polling for updates, especially when clients are designed to check endpoints for changes every few seconds. This approach can quickly multiply the number of requests sent to the server, rapidly pushing you over API rate limiting thresholds. Even well-intentioned monitoring tools or integration scripts often fall into this trap. For example, when each client polls a status endpoint every two seconds, a handful of users can generate thousands of requests per minute, easily surpassing common limits like 1000 requests per minute per user enforced by many APIs.
Poor pagination handling is another frequent cause of excessive request volume. When clients treat each paginated response as a cue to immediately fetch the next page – without any pacing, batching, or delay – they can inadvertently flood the API. This is especially problematic for endpoints returning large data sets, as a single high-volume operation might involve dozens or hundreds of sequential calls in rapid succession.
Many developers trip rate limits during load testing because these patterns are not obvious until tests simulate real-world usage at scale. The LoadFocus guide on API performance testing challenges details how improper pagination and polling can skew load test results and obscure real bottlenecks.
Smarter Alternatives
- Adopt webhooks for event-based updates instead of polling when the API supports them.
- Use batch pagination or increase page size to reduce the total number of requests.
- Implement request pacing or exponential backoff between page fetches to avoid spikes.
For a deeper dive into best practices and common issues, LoadFocus’s diagnostic guide to API performance issues outlines how to identify and resolve these patterns before they undermine load test validity.
5. Lack of Exponential Backoff or Throttling Algorithms
When it comes to API rate limiting, the difference between a successful load test and a flood of error responses usually comes down to how clients handle retries. Too often, developers default to blunt linear retries – banging the same API endpoint every second, regardless of what the server is signaling. This approach not only increases the odds of hitting a rate limit, it can push a struggling backend into total overload. The fix is well-known in theory but poorly executed in practice: implement exponential backoff – ideally with some randomization (jitter) mixed in.
Key Insight: The absence of exponential backoff or intelligent throttling is one of the fastest ways to trigger – and worsen – API rate limiting during load testing and production traffic spikes.
Let’s dig into why these algorithms matter, how they work, and what actually happens when you ignore them.
What Happens When Clients Hammer APIs Without Backoff?
Most APIs have hard-coded thresholds – say, 1000 requests per minute per user. Go even a few percent over that, and you’ll hit 429 errors or get throttled. But the real trouble starts when your client (or load testing tool) gets a “retry later” response and immediately tries again, or, worse, retries on a fixed interval without any pause. This is classic linear retry logic, and it turns a temporary hiccup into a denial-of-service scenario.
Exponential backoff solves this by spacing out retries: the wait time doubles (or grows by another factor) each time the request fails. Jitter adds randomness to avoid “thundering herd” problems when thousands of clients wake up at the same millisecond and retry in unison. Without these mechanisms, even a modest test can trigger rate limits almost instantly – wasting your test run and making it impossible to gauge real-world limits. For a deeper dive into common API performance issues caused by poorly behaved clients, see this analysis on detecting API performance issues.
Backoff and Throttling: Which Strategy, When?
There’s no one-size-fits-all approach. The best backoff algorithm for your load test or monitoring tool depends on the API’s policies, your business requirements, and the risk of collateral damage if you go over limits. Some APIs even require client-side throttling by policy: you can only send, for example, a burst of 10 requests per second, regardless of what your test rig is capable of. Ignoring this doesn’t just risk errors; it can get your account suspended.
| Backoff Strategy | Complexity | Typical Use Case | Limitation |
|---|---|---|---|
| Exponential Backoff | Medium | APIs with variable load, risk of bursts | Can result in long delays if max retries are high |
| Exponential Backoff + Jitter | High | Distributed systems, high concurrency clients | Harder to debug, retry intervals unpredictable |
| Linear Backoff | Low | Legacy APIs, simple scripts | Still risks synchronized retries, less resilient |
| Fixed Throttle (Client Side) | Low | APIs with explicit per-client rate caps | Wastes throughput if limits are dynamic |
| No Backoff | None | Ad hoc test scripts, naive implementations | Almost guaranteed to trigger rate limiting |
Implementing Backoff: Practical Considerations
Building backoff into your load testing scripts or API clients is more than just slapping a sleep timer after a failed request. Start by reading and respecting retry-after headers – these tell you when it’s safe to try again. Then, model your retry logic to double the interval after each failure, with an upper cap. For distributed tests, always add jitter to break up synchronized retries. Most modern load testing platforms, like LoadFocus, make it easy to simulate these patterns across hundreds or thousands of concurrent users. For a guide on how to structure load tests that respect real-world API constraints, see this API load testing tutorial.
Watch for “retry storms” in your logs: spikes of requests right after a rate limit window resets. This is a dead giveaway that your backoff isn’t random enough. Monitoring these patterns can help you fine-tune your strategy – something we’ve seen repeatedly in large-scale performance testing engagements. If you’re looking for more ways to optimize your API testing workflows, the 2026 API performance optimization guide is worth a read.
Ignoring these best practices doesn’t just get you throttled; it ruins the accuracy of your test results and makes it impossible to understand the true limits of the system you’re testing. Thoughtful backoff and throttling aren’t optional – they’re table stakes for any serious API performance effort.
6. Shared API Credentials Across Multiple Test Clients
Why Single Credentials Hit API Rate Limits Sooner
When multiple test clients use the same API key or token, every request they make is pooled under a single identity. This means all traffic counts toward one set of API rate limiting thresholds, such as a strict 1,000-requests-per-minute policy. In practice, you hit the provider’s limit far sooner than expected, especially during load testing or burst scenarios. The provider sees the combined activity as if it’s coming from a single user, so it triggers throttling or outright rejections much faster.
The Advantage of Distributed Credentials
Some API providers allow distributing load across multiple tokens or keys for testing purposes. Assigning a unique credential to each client or logical user can spread the requests, reducing the likelihood that any one key exceeds its quota. This approach is especially useful in load testing tools like LoadFocus, where the goal is to simulate real-world peak traffic patterns without immediately running into artificial bottlenecks. For a deeper look at distributed load strategies, see this case study on reducing API latency through distributed load testing.
Provider Restrictions and Best Practices
However, it’s critical to check your provider’s terms. Many prohibit token splitting for production use, reserving multiple credentials solely for non-production or internal testing. Violating these policies can lead to revoked access or even contract issues. Instead, focus on optimizing client behavior: batch requests, respect rate limit headers, and monitor usage patterns. For more on optimizing API usage, review our guide on common API performance issues.
Thoughtful credential management is not just about bypassing limits – it’s about building fair, scalable, and compliant test scenarios. When done right, you gain more accurate insight into how APIs handle real traffic, and you avoid misleading failures during load tests.
7. Provider-Side Adaptive or Burst Rate Limiting Models
Most engineers associate API rate limiting with simple, rigid request ceilings – think “1000 requests per minute per user” – but modern providers have moved well beyond that. The reality is that adaptive and burst-friendly algorithms, like token bucket or leaky bucket models, dominate today’s API platforms. These approaches allow short spikes in traffic without immediately penalizing clients, which fundamentally changes how load testing results must be interpreted.
How Burst-Friendly Algorithms Work
Unlike fixed-window limits, which reject any request over the threshold within a set timeframe, token bucket algorithms offer a more nuanced control. Picture a bucket constantly refilled with tokens (representing allowed requests) at a steady rate. Clients can “spend” these tokens in quick succession for a burst, but once the bucket is empty, requests are throttled until more tokens accumulate. Leaky bucket models operate similarly, but they smooth traffic by only allowing a fixed outflow rate, even if a spike of requests arrives together.
For example, suppose an API offers 1000 requests per minute per user. With a strict limit, 1001 requests in a minute means the last one is denied. With a token bucket, you might send 100 requests in one second (if enough tokens are available), but if you maintain that pace, you’ll eventually hit a wall. The model enforces a long-term average but tolerates brief bursts – exactly the sort of behavior you see during launch events or sudden user surges.
Dynamic Throttling and Smart Rate Limits
Some providers have taken things further, implementing dynamic rate limiting that adapts in real time. The threshold might increase for premium subscribers, or tighten temporarily if backend load climbs. Others monitor user patterns and adjust limits based on actual risk or historical behavior. For teams running advanced load and performance tests with LoadFocus, this means you may see different outcomes depending on the time of day, system health, or even your account’s reputation.
This sophistication is designed to balance protection and access. For instance, an e-commerce API might allow brief order surges but clamp down if traffic shows signs of abuse. For more context on how these mechanisms affect real-world load tests, see Top 6 API Performance Testing Challenges (and How to Solve Them Effectively in 2026).
How Adaptive Models Change Test Interpretation
Here’s where load testing gets tricky: if your test sends a spike of requests in a short window, burst-friendly APIs may pass with flying colors. The same test, stretched into a sustained high-throughput scenario, can fail dramatically once the long-term average kicks in. It’s not a bug in your test, nor is it a flaw in the provider – it’s a deliberate feature of adaptive rate limiting.
For example, you might configure LoadFocus to hammer an endpoint with 500 requests in the first 10 seconds and see no throttling. But keep that pace up for several minutes, and you’ll likely hit a wall as the rate limit algorithm drains the token pool. This distinction is critical for interpreting your results and for setting realistic performance objectives during load testing.
Documentation as a Test Design Weapon
Provider documentation is your best defense against misreading results. Detailed docs will state not just the numeric limit, but the algorithm type – token bucket, leaky bucket, fixed window, dynamic quota – and clarify how bursts are handled. If you skip this step, your load tests may look “successful” for brief periods but fail to reflect the actual experience of a client running at scale. In practice, this means mapping your test patterns to the real-world traffic your users generate, and adjusting your interpretation accordingly.
One overlooked benefit of platforms like LoadFocus is their ability to simulate both burst and sustained load, making it easier to pinpoint how advanced rate limiting models impact your API’s reliability and user experience. If your goal is to surface subtle throttling behaviors before they affect production users, this level of test realism is hard to achieve any other way.
8. Subscription Tier or Quota Restrictions
Why Your Subscription Level Matters
API rate limiting isn’t just a technical issue – it’s often shaped by your subscription tier or the specific quota negotiated with the provider. Many testers overlook this, running load tests on free or trial accounts and assuming they’ll get the same results in production. In reality, paid tiers usually include higher or adjustable rate limits – sometimes dramatically so. For example, a public API might throttle requests at 1,000 calls per minute for trial users, but offer increased quotas for enterprise clients after negotiation. Testing below your intended tier can mask bottlenecks or create false positives that never arise for paying customers.
The Pitfall of Testing on Free or Trial Plans
If you’re evaluating performance using a sandbox or free account, chances are you’re not seeing the real-world constraints your production environment will face. This can lead to misleading results – either underestimating what your app can handle, or assuming stability that won’t hold under actual usage. It’s not uncommon for companies to only discover these differences after deployment, when real users hit higher thresholds and receive a wave of 429 errors or unexpected throttling. LoadFocus’s recent case study on distributed load testing highlights how quota thresholds can impact latency and error rates under heavy load.
Negotiating for Higher Quotas
In enterprise scenarios – especially where mission-critical workflows depend on sustained high-volume API access – simply accepting default limits is rarely enough. Negotiating higher quotas or custom rate limits with your provider is not just possible but often essential. Some providers offer dedicated endpoints, whitelisting, or Service Level Agreements (SLAs) for approved partners. When planning load tests, make sure you’re mimicking your production tier and – if needed – open a dialog about raising your limits. For more advanced strategies on simulating real-world API quotas, see how teams solve API performance testing challenges in practice.
9. Infrastructure or Middleware Bottlenecks Mistaken for Rate Limiting
Seeing a flurry of 429 errors during load testing might seem like textbook API rate limiting, but real-world failures are not always so clear-cut. Infrastructure components – including proxies, CDNs, and web application firewalls (WAFs) – can mask or mimic rate limiting by introducing their own restrictions. If you jump to conclusions about the source of request failures, you risk wasting hours on the wrong root cause and missing out on critical performance insights.
It’s surprisingly common for network-level elements to block or throttle requests for reasons unrelated to API provider policies. For example, a cloud-based proxy may time out connections under heavy load, or a CDN might enforce its own request-per-second limits. WAFs can block bursts of automated traffic based on security rules, returning 429s or 403s even when the API backend is not rate limiting at all. These infrastructure-imposed limits can look just like a provider’s rate limiting from the client side, but the underlying issues – and solutions – are very different.
To address these scenarios, careful log analysis and monitoring become essential. Instead of focusing only on API error codes, analyze network traces and correlate failures across different infrastructure layers. LoadFocus’s guide to detecting common API performance issues offers practical methods for surfacing these bottlenecks with real-time metrics and targeted tests. If you want to see how distributed testing can help isolate bottlenecks across your stack, the case study on reducing API latency through distributed load testing is a solid reference.
Table: Rate Limiting vs. Infrastructure Failures
| Symptom | Observed Error Codes | Typical Cause | Diagnostic Steps | Resolution Tactics |
|---|---|---|---|---|
| Consistent 429 with “Retry-After” header | 429 | Provider-side API rate limiting | Check API documentation, inspect response headers | Implement backoff, optimize request patterns |
| Random 429/403s, often with no “Retry-After” | 429, 403 | WAF or security proxy rules | Review firewall/proxy logs, test from different IPs | Adjust WAF rules, whitelist test clients |
| Sudden connection drops or timeouts at peak load | 504, connection reset | Proxy or CDN timeout | Inspect CDN/proxy logs, compare latency metrics | Increase timeout settings, scale edge nodes |
| Errors only from certain geographies or IP ranges | 403, 429, 502 | Geo-blocking or CDN-based throttling | Test from multiple locations, review CDN policies | Adjust CDN config, consult provider support |
Distinguishing between true API rate limiting and infrastructure bottlenecks is a skill every API tester needs. Without this clarity, you might optimize the wrong layer or miss a configuration tweak that unlocks far better performance. For a deeper dive into testing strategies that expose these nuanced issues, see LoadFocus’s complete guide to API testing in 2026.
10. Inadequate Monitoring and Alerting During Load Testing
Why Blind Spots Lead to Missed Rate Limiting Events
When you run load tests against an API, real-time monitoring isn’t optional – it’s the difference between catching API rate limiting issues as they happen or missing them until your test results are nearly useless. Without granular visibility into requests, responses, and error codes, rate limit breaches can slip past your radar. You might notice a sudden spike in failed requests long after the actual limit was reached, making it hard to pinpoint the root cause. Worse, some teams misattribute those failures to infrastructure glitches or test data problems, burning precious time on the wrong diagnosis.
Modern load testing dashboards now provide instant feedback on rate limit violations. They highlight not just raw counts, but also patterns – such as clustering of HTTP 429 errors, the timing of throttling events, and whether certain endpoints or users are being throttled more aggressively. This level of detail is crucial, especially as API rate limiting strategies have grown more sophisticated, with providers using algorithms like token bucket or dynamic, user-tiered thresholds. If your monitoring can’t break down errors by user key, endpoint, and time window, you’re flying blind.
Continuous Monitoring for Faster Remediation
Effective monitoring enables rapid root cause analysis. Instead of waiting for post-test log reviews, you get alerts in real time – meaning you can react while the test is still running. This is particularly useful for pinpointing issues like excessive request bursts, which often trigger throttling before you hit your overall traffic goal. For a concrete illustration of how sophisticated monitoring tools can reduce API latency and catch performance bottlenecks early, see this case study on distributed load testing.
Choosing a dedicated API monitoring solution, such as LoadFocus’s cloud-based API monitoring, can dramatically reduce your feedback loop. These tools provide customizable alerts, detailed dashboards, and integrations with your existing workflows, so teams can spot issues the moment they emerge.
If you’re still relying on log scraping or basic metrics, it’s time to rethink your approach. Granular monitoring and alerting are not just best practices – they’re foundational for accurate, actionable API load testing.
How to Choose: Decision Framework for Handling API Rate Limiting
Practical Steps for Mitigation Strategy Selection
API rate limiting isn’t just a technical hurdle – it’s a constraint that shapes your testing approach, development workflow, and often, your business relationships. You need a pragmatic, stepwise framework to decide whether to tweak your client logic, negotiate for higher limits, or redesign your tests altogether.
Start by clarifying your test objective. Are you simulating realistic production traffic, stress-testing upper bounds, or validating graceful error handling? Then identify the type of rate limiting in play. Is the API enforcing a simple requests-per-minute cap, or have you run into a token bucket algorithm that lets you burst for a few seconds before throttling kicks in? Each scenario requires a different mitigation tactic.
Decision Table: Matching Situation to Action
| Situation | Recommended Action | Limitation | Tools/Links |
|---|---|---|---|
| Hitting fixed per-user or per-key limits (e.g., 1000 requests/minute) | Distribute load across multiple API credentials or keys. If policy allows, rotate keys to avoid tripping individual caps. | Credential rotation may violate API terms; coordination overhead increases with scale. | API performance testing challenges |
| Receiving “429 Too Many Requests” with a Retry-After header | Implement exponential backoff retry logic. Respect the Retry-After period before sending new requests. | Prolongs test duration. Risk of synchronized retries if all clients respond to header identically. | API tester guide |
| Encountering burst rate limits (token bucket/leaky bucket) | Throttle client request rate to stay within both sustained and burst limits; use request pacing algorithms. | Limits insight into true stress capacity; risk underestimating system resilience under real spikes. | Load test RESTful APIs |
| Need to exceed published quota for legitimate testing or business reasons | Contact provider to negotiate a higher rate limit or request a dedicated testing environment. | Provider may deny request or impose additional costs; process can take time. | Provider documentation/support |
| Unclear rate limiting algorithm; inconsistent throttling observed | Analyze API headers and logs; use a tool like LoadFocus’s free API load test to experiment and document limits empirically. | Time-intensive manual analysis; may not capture changes in dynamic limits. | LoadFocus free API load test |
Guiding Your Next Steps
Testers shouldn’t stop at diagnosis. Once you’ve identified the rate limiting scenario, move directly to actionable mitigation. Implement retry logic where headers dictate, distribute credentials when policies allow, or escalate with your provider if your use case warrants a higher quota. Tools like LoadFocus’s free API load test let you safely probe real-world limits before committing to large-scale changes.
For more on practical performance strategies, see the API performance testing challenges guide and the comprehensive API tester walkthrough. The right mitigation starts with understanding both the test environment and the provider’s policies – there’s rarely a single right answer, but the wrong one is doing nothing and hoping the limits disappear.
Frequently Asked Questions
How can I tell if I’m hitting API rate limits during load testing?
Look for a spike in HTTP 429 errors or a drop in response quality. Monitoring tools that track rate limit headers can provide real-time alerts.
What is the difference between static and dynamic API rate limiting?
Static limits are fixed caps on requests, while dynamic limits adjust based on factors like current load or user behavior, allowing more flexibility.
How do I avoid redundant API calls in automated tests?
Use batching and caching to reduce unnecessary requests. Analyze test scripts for repeated calls and optimize logic to minimize redundancy.
What is exponential backoff and how do I implement it?
Exponential backoff is a retry strategy that increases wait time between attempts. Implement it by doubling the delay after each failed request, adding randomness to avoid synchronized retries.
When should I request higher API rate limits from a provider?
Request higher limits if your application has legitimate high-volume needs, especially during critical events. Provide detailed use cases to support your request.
Can infrastructure issues mimic API rate limiting errors?
Yes, components like CDNs or WAFs can introduce their own limits, causing errors similar to rate limiting. Analyze logs and network traces to identify the true source.
What monitoring tools help detect API rate limiting in real time?
Tools like LoadFocus provide real-time monitoring and alerts for rate limit breaches, helping you adjust tests on the fly.
How does API rate limiting differ across SaaS, public, and internal APIs?
SaaS APIs often have strict public limits, while internal APIs may offer more flexibility. Public APIs enforce limits to ensure fair usage among all clients.
Understanding and respecting API rate limiting is not just about compliance – it’s about building resilient, user-friendly systems that scale reliably under real-world conditions.
Powered by PostNext service