Key takeaways
- A baseline turns future runs into comparisons instead of isolated numbers.
- Capture it on a stable build under representative load, then leave it alone.
- Run the baseline test more than once: the spread between runs tells you how big a change has to be before it means anything.
- Re-baseline deliberately after a genuine improvement or an infrastructure change, not after every run.
A performance baseline is a recorded set of measurements (response time percentiles, throughput, error rate and server resource use) taken from a known-good version of your application under a defined, repeatable load. Baseline testing in performance testing means running that load test once you trust the build, saving the results, and comparing every later run against them. To create one quickly: pick the endpoints or user journeys that matter, model a normal-day workload, run the test three times on a stable build, and store the results with the build and environment details.
What is a performance baseline?
A performance baseline is a snapshot of how your application performs under normal, known conditions, kept as the reference for later measurements. The ISTQB performance testing syllabus describes it as “a set of metrics used to compare current and previously achieved performance measurements”. A baseline holds no goals or targets. It is what you measured, so it tells you whether a change made things faster, slower or no different.
There are two kinds, and teams often mix them up:
- A production baseline comes from monitoring real traffic (APM, real user monitoring, server metrics) over a period long enough to cover your traffic cycle, usually at least a full week so weekdays and weekends are both in it.
- A load test baseline comes from a controlled test run: the same script, the same load and the same environment every time. It is what most people mean by baseline testing, and it is the one this guide is about. Use the production numbers to design its workload.
What is baseline testing in performance testing?
In software testing generally, a baseline is an agreed reference that later versions are checked against: a reviewed specification, a set of expected outputs or earlier measured results. In performance testing, baseline testing is the run that produces that reference: a full run of a performance test on a version you trust, done to produce the numbers that every later run is compared with. It is usually a normal-load test, not a stress test. Grafana’s k6 guides call this an average-load test, one that simulates “the average amount of activity on a typical day in production”. The ISTQB syllabus says the results of a baseline test serve as a “snapshot” of system performance and form “the basis of comparison with subsequent tests”.
Baseline, benchmark and SLO are three different numbers, and it helps to keep them apart:
| Term | What it is | Example |
|---|---|---|
| Baseline | What you measured on a known-good build, under a defined load | p95 412 ms at 50 requests per second |
| Benchmark or target | What you want to achieve, often from users, the business or competitors | p95 under 500 ms |
| SLO or threshold | The rule that passes or fails a run | Fail if p95 is over 500 ms or errors are over 1% |
A baseline without a target tells you that something changed but not whether it matters. A target without a baseline tells you whether you pass, but not whether the last release made things worse. You want both. Our guide to setting performance benchmarks for web applications covers the target side.
How are application performance baselines created?
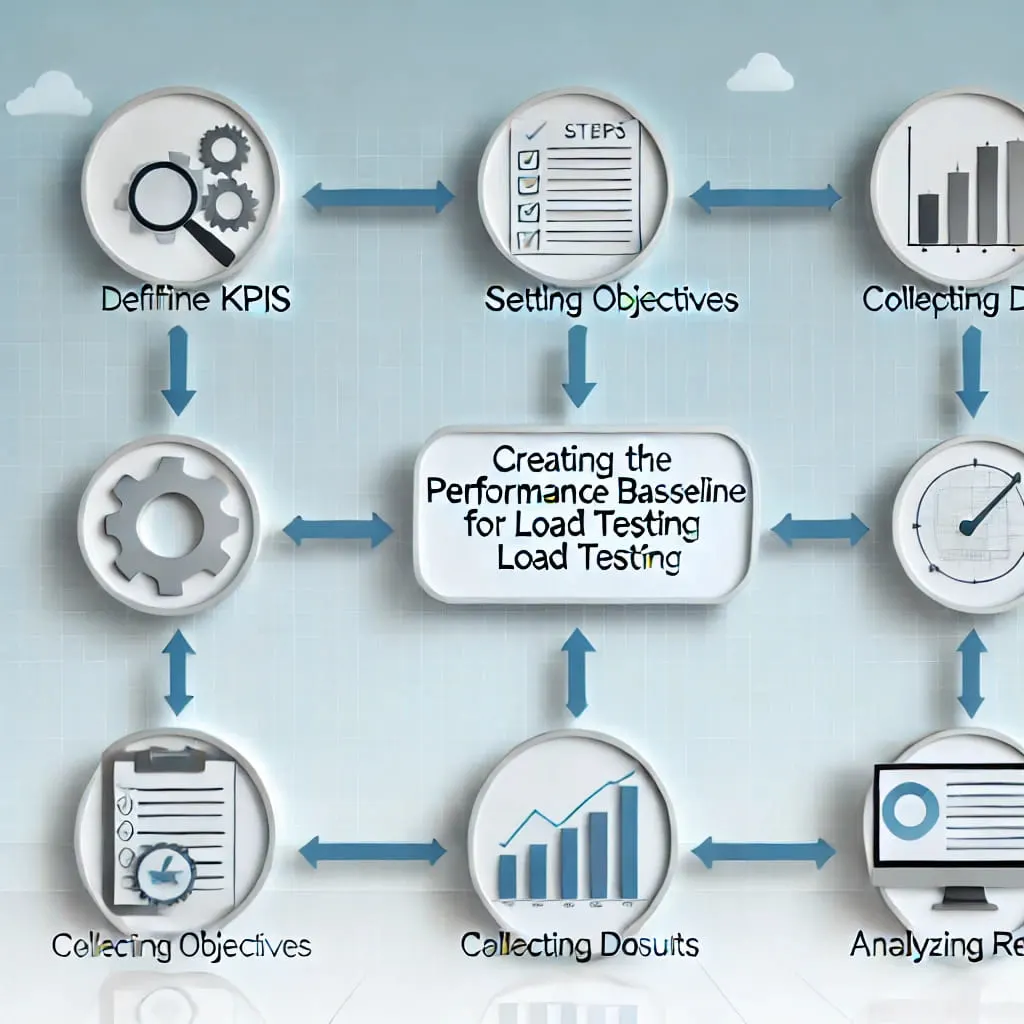
- Choose the scope. Pick the endpoints or user journeys that matter most: login, search, checkout, the busiest API calls. A baseline per endpoint is more useful than one for the whole site, because a regression in one call disappears in a site-wide average.
- Model a normal-day workload from production data. Take the request rate and the mix of endpoints from your analytics or access logs for a typical busy hour. Write the test so it reproduces that rate and that mix, with think time between steps.
- Freeze the environment. Same build, same configuration, same instance sizes, same data volume, same test region. Write all of it down; a baseline is only valid for the setup it was measured on.
- Check the script first. Run a short smoke test with a handful of users to confirm every request returns what it should. A baseline full of 401s or redirects measures the wrong thing.
- Run the baseline test with a ramp and a steady state. The k6 average-load guide suggests a ramp-up of about 5% to 15% of the total test time and a steady state at least five times longer than the ramp. Only the steady-state part belongs in the baseline.
- Repeat it. Run the same test at least three times, ideally at different times of day. The spread between runs is your noise level.
- Record the results with their context. Store the percentiles, throughput, error rate and resource figures per endpoint, together with the build, the date, the load and the environment. The ISTQB syllabus lists the start date and time, the concurrent user goal, the throughput measured and key findings such as error rate and response time. Put the baseline and how to reproduce it in your performance test plan.
Which metrics belong in a performance baseline?
Record percentiles of response time, not only the average: the median (p50), p95 and p99 per endpoint. Averages hide the slow tail that users notice, as percentiles versus averages explains. Add throughput (requests per second actually served), error rate split by status code, and the number of concurrent users at each point.
On the server side, record CPU, memory, garbage collection, connection pool use and database query times during the steady state. These tell you why a later run differs. A run with the same response times but twice the CPU is a regression waiting to happen.
How to build an endpoint performance baseline with JMeter
Apache JMeter (5.6.3 is the current release) reports results per sampler label, so give each request a clear, unique name: GET /api/products, POST /api/cart. The Summary Report and Aggregate Report create one row per label, and the Aggregate Report adds the median and the 90%, 95% and 99% lines. Two identical requests with different labels end up as separate rows, which is what you want for an endpoint baseline.
Run the baseline from the command line, not the GUI, and generate the HTML dashboard from the same run:
jmeter -n -t baseline.jmx -l baseline-run1.jtl -e -o report-baseline-run1/Keep the .jtl file: it is the raw data you will compare later runs with. Remove the View Results Tree listener before the run. The JMeter manual says it “MUST NOT BE USED during load test”, because it uses a lot of memory and CPU and skews the results on the load generator. Use it only while building the script.
How do you compare new runs against the baseline?
Compare the same metric, for the same endpoint, under the same load. Then decide on a tolerance before you look. The tolerance has to be wider than the spread you saw between your baseline runs, or ordinary noise will look like a regression.
An illustrative example with made-up numbers: three baseline runs of the checkout endpoint give a p95 of 410 ms, 432 ms and 395 ms. The mean is 412 ms and the spread is 37 ms, about 9% of the mean. A tolerance of 10% (p95 up to about 453 ms) sits just outside the noise. A new release at 445 ms is within it. A release at 520 ms is a real regression worth investigating.
Look at the whole result, not only the summary row. Check whether errors started at a particular load, whether throughput dropped while response times climbed, and whether one endpoint moved while the others stayed flat. The baseline comparison walkthrough shows how to set this up between two LoadFocus runs.
An example: baselining a checkout before a sale
This is an illustrative scenario, not a customer story. A shop expects a seasonal sale and wants to know whether the latest release is ready.
The team takes the busiest normal hour from its analytics, about 30 orders per minute across browse, cart and checkout, and builds a test that reproduces that mix. It runs the test three times on the current production build and records a checkout p95 of around 1.5 seconds with no errors. That is the baseline. A second test at the expected sale traffic then shows checkout p95 rising to about 5 seconds, with timeouts appearing as load passes a certain number of users. After the team tunes the database connection pool and the web server workers, the sale-load test comes back at about 2 seconds. A new normal-load run confirms that the everyday numbers did not get worse. That normal-load run becomes the new baseline.
Common mistakes when creating a performance baseline
- Baselining a bad run. A run with errors, a cold cache or a noisy neighbour on shared hardware becomes the standard everything is judged against. Use a run you trust and can reproduce, not the fastest one you ever saw.
- One run only. Without repeats you cannot tell a 5% change from noise.
- Changing two things at once. A new build on a new instance type gives you a new baseline, not a comparison.
- Ignoring the environment. Staging with a tenth of production’s data will not produce production’s query times. Note the difference, or test with realistic data volumes.
- Load from one place only. Network latency and CDN behaviour vary by region. Run the baseline from the regions your users are in, and compare runs from the same regions.
- Forgetting third parties. Payment, search or auth services you call can shift your numbers without any change on your side. Record which external calls the test makes.
When should you update a performance baseline?
Update it on purpose, not on every run. Good reasons are a verified performance improvement that you want to protect, an infrastructure change (new instance types, a new database version, a CDN switch), a significant change in real traffic patterns, or a redesign of the user journeys under test. After each update, keep the old baseline and note why it changed. When response times slowly drift up over several releases, the history of baselines is what shows it.
Setting a baseline in LoadFocus
In LoadFocus load testing, open the results of the run you trust and click Set Baseline. Every other run of the same test is then compared with it, with the differences shown as percentages. To change it, set a different run as the baseline. To remove it, click the green check on the current baseline run. The baseline comparison page walks through each step.
To turn the baseline into an automatic check, set pass/fail thresholds on the test: maximum p95 and p99 response time, maximum error rate and minimum throughput. Every run then gets a pass or fail verdict, and a chart shows p95, error rate and throughput across all runs of the test with the thresholds drawn on it. On paid plans you can schedule a saved test hourly, daily, weekly or monthly, so the comparison runs without anyone starting it. Tests run from 25 cloud regions, and you can upload an existing JMeter or k6 script instead of building the test in the browser.
Frequently Asked Questions
How do you do baseline performance testing?
Pick the key endpoints or journeys, model a normal-day workload from production data, and run that load test on a stable build in a fixed environment. Repeat it at least three times, record percentiles, throughput, error rate and server resources with the build and environment details, and compare every later run against those numbers.
What is the difference between a baseline and a benchmark?
A baseline is what you measured on a known-good version. A benchmark, or target, is what you want to achieve. You compare new runs against the baseline to catch regressions, and against the target to decide whether performance is good enough.
How long should a baseline test run?
Long enough for a steady state after the ramp-up. The Grafana k6 average-load guide suggests a ramp of about 5% to 15% of the total time and a steady state at least five times longer than the ramp. Caches and connection pools then have time to warm up before you measure.
How do you automate performance testing against a baseline?
Run the same test on a schedule or from your CI/CD pipeline, with pass/fail thresholds based on your baseline and targets. JMeter can run from the command line in any pipeline. In LoadFocus, thresholds give each run a verdict, and scheduled runs repeat the test without manual starts.
How often should you re-baseline?
Only after a deliberate change you have verified: a performance improvement, new infrastructure, or a big shift in traffic patterns. Re-baselining after every run hides slow regressions, because each small slowdown becomes the new normal.
Sources
- ISTQB, Certified Tester Performance Testing syllabus v1.0, sections on baseline values in the test plan and baseline test results in reporting, read October 2026.
- Grafana k6 documentation, Average-load testing (grafana.com/docs/k6/latest/testing-guides/test-types/load-testing) (typical-day load, ramp-up 5% to 15%, steady state at least five times the ramp), read October 2026.
- Apache JMeter component reference (Summary Report, Aggregate Report, View Results Tree) and generating the dashboard report (
-n -t -l -e -o), read October 2026.